Back to top

Image Demo

Video Demo

Quantitative Results


ZEUS: Accelerating Diffusion Models with Only Second-Order Predictor

1Duke University  2University of Florida  3Google DeepMind 
(* indicates equal contribution)
  ZEUS plugs straight into any project built on HuggingFace Diffusers 🤗
ACM Multimedia 2026 · Oral

ZEUS adds essentially zero overhead, no feature caches, and no architectural modifications, and it is compatible with different backbones, prediction objectives, and solver choices.

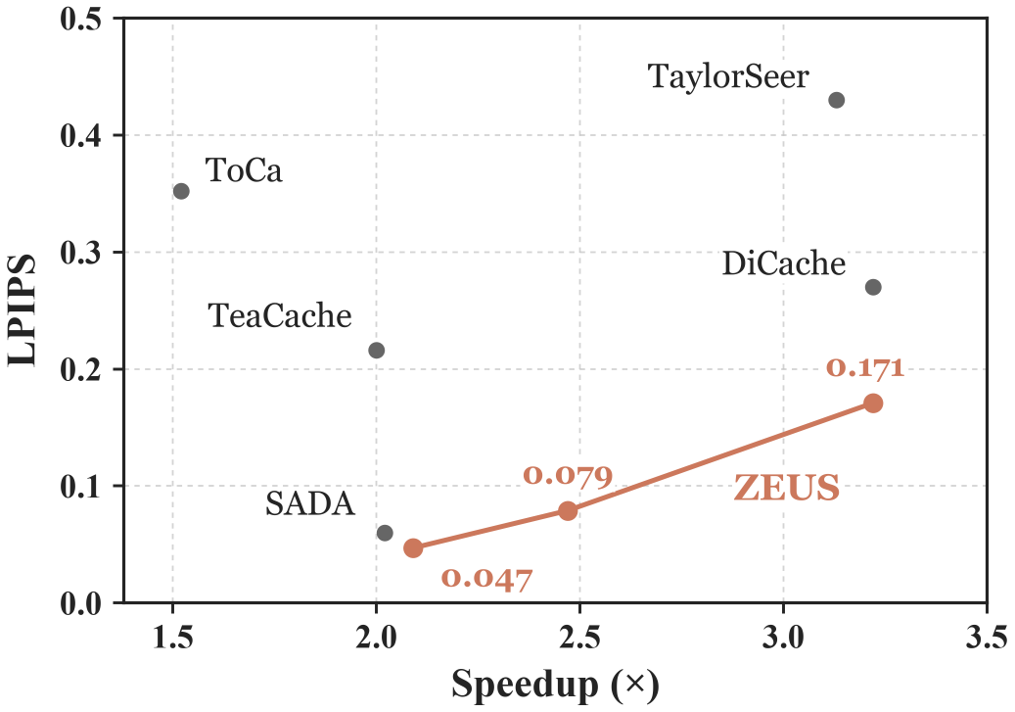
FLUX.1-dev speedup versus LPIPS: ZEUS-Medium 2.09×/0.047; Fast 2.47×/0.079; Turbo 3.22×/0.171.

FLUX.1-dev

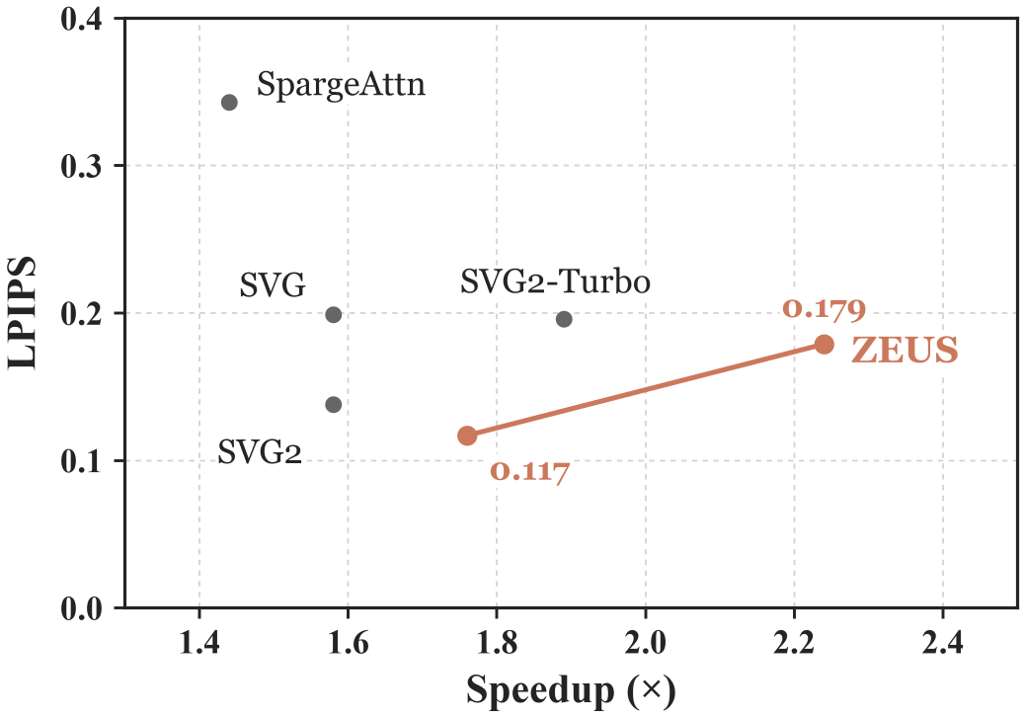
Wan 2.1 speedup versus LPIPS: ZEUS 1.76×/0.117; ZEUS-Fast 2.24×/0.179.

Wan 2.1

Figure 1. Speed–fidelity results on FLUX.1-dev and Wan 2.1. Higher speedup and lower LPIPS are better. ZEUS reaches 3.22× speedup on FLUX.1-dev and 2.24× on Wan 2.1.

Meet ZEUS

Denoising generative models deliver high-fidelity generation but remain bottlenecked by inference latency due to the many iterative denoiser calls required during sampling. Training-free acceleration methods reduce latency by either sparsifying the model architecture or shortening the sampling trajectory. Current training-free acceleration methods are more complex than necessary: higher-order predictors amplify error under aggressive speedups, and architectural modifications hinder deployment.

Beyond 2x acceleration, step skipping creates structural scarcity—at most one fresh evaluation per local window—leaving the computed output and its backward difference as the only causally grounded information. Based on this, we propose ZEUS, an acceleration method that predicts reduced denoiser evaluations using a second-order predictor, and stabilizes aggressive consecutive skipping with an interleaved scheme that avoids back-to-back extrapolations.

ZEUS adds essentially zero overhead, no feature caches, and no architectural modifications, and it is compatible with different backbones, prediction objectives, and solver choices. Across image and video generation, ZEUS consistently improves the speed–fidelity performance over recent training-free baselines, achieving up to 3.2x end-to-end speedup while maintaining perceptual quality. The code is publicly available at github.com/Ting-Justin-Jiang/ZEUS.
A Tale: Lightning of ZEUS

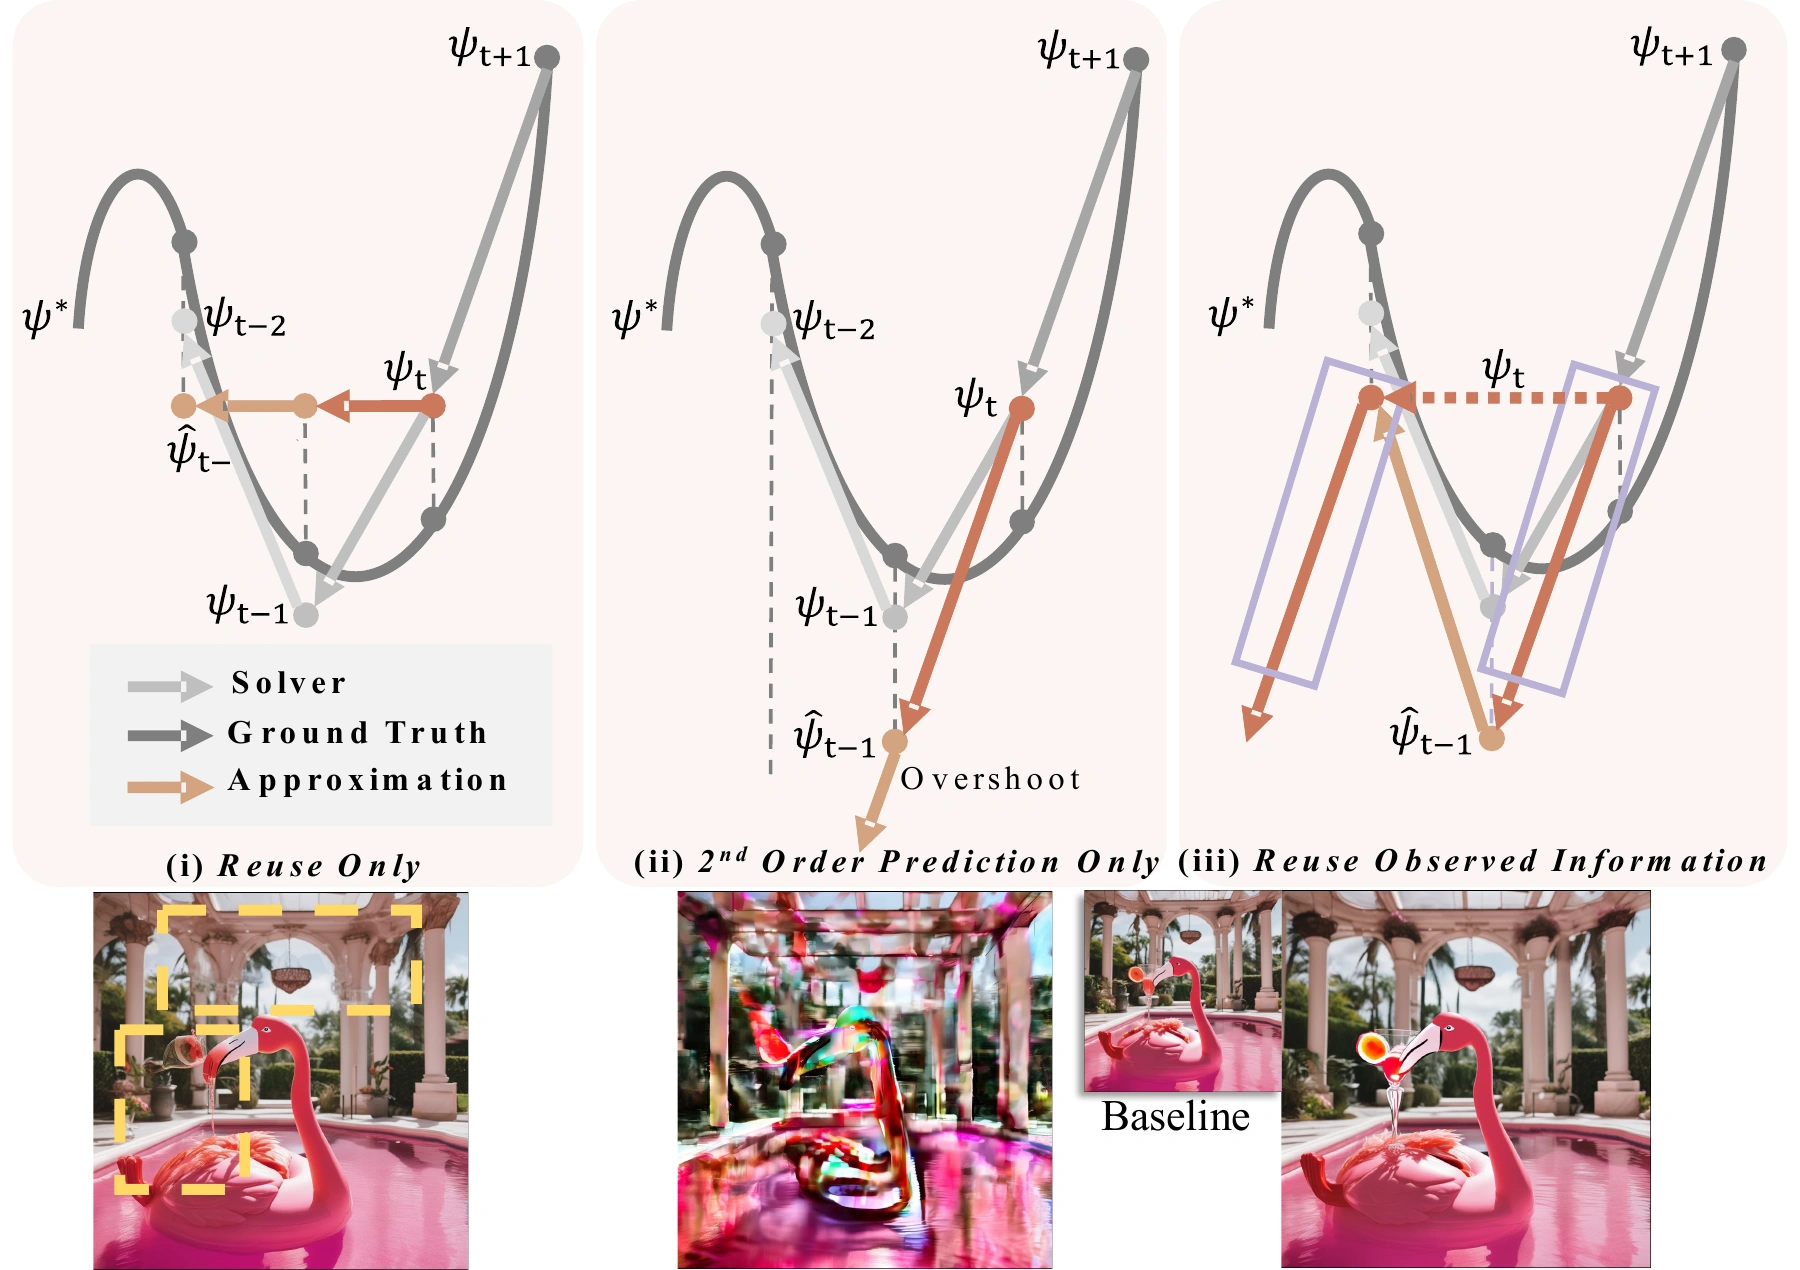
At step $t$, the denoiser has computed $\psi_t$. The backward difference $\Delta^{(1)}\psi_t = \psi_t - \hat{\psi}_{t+1}$ encodes information that $\psi_t$ alone cannot provide—the response of the denoiser to the given (approximated) state. Together, the pair constitutes the observed information set, available at zero marginal cost.

Given the observed information set, we can add the elements together, which forms a second-order predictor:

$\hat{\psi}_{t-1} = \psi_t + \Delta^{(1)}\psi_t = 2\psi_t - \hat{\psi}_{t+1}.$

Rather than computing new approximations, we simply cycle between the full evaluation and its second-order extrapolation. This interleaved pattern applies the second-order predictor once (at $j=1$), then resets to $\psi_t$, then reuses the same pair—never chaining predictions.

Paper comparison of reuse-only, predictor-only, and ZEUS observed-information reuse

Figure 2. Three approximation schemes from the camera-ready paper. Left: Reuse-only is stable but loses fine detail. Middle: Chaining second-order predictions overshoots. Right: ZEUS alternates reuse of the observed information pair to prevent overshoot and preserve detail.

How ZEUS Fly

ZEUS uses a second-order numerical predictor that extrapolates the next denoiser output from the observed information set at the most recent full-evaluation step. Its interleaved scheme reuses the same pair across consecutive reduced steps, as shown in Figure 3.

Model Solver Model Model Solver Solver Bypass Bypass ... ... If continue skip... xₜ xₜ₋₁ xₜ₋₂ ψₜ ψₜ₋₁ ψₜ₋₂

Swipe horizontally to view the full animation.

Figure 3. Overview paradigm of ZEUS .

Evaluations

All experiments use official checkpoints, HuggingFace Diffusers, FP16 precision, and 50 sampling steps unless otherwise noted. All runs are performed on a single NVIDIA A100-80GB GPU. We report end-to-end wall-clock speed up.

Images

The original qualitative examples are shown below. Their preset labels refer to this demonstration; measured camera-ready speedups and metrics are reported in the quantitative results below. Playback timing is illustrative.

Qualitative example, demonstration 1 Qualitative example, demonstration 1 Qualitative example, demonstration 1 Qualitative example, demonstration 1 Qualitative example, demonstration 1 Qualitative example, demonstration 1 Qualitative example, demonstration 1 Qualitative example, demonstration 1 Qualitative example, demonstration 1

Original

Qualitative example, demonstration 2 Qualitative example, demonstration 2 Qualitative example, demonstration 2 Qualitative example, demonstration 2 Qualitative example, demonstration 2 Qualitative example, demonstration 2 Qualitative example, demonstration 2 Qualitative example, demonstration 2 Qualitative example, demonstration 2

Balanced

Qualitative example, demonstration 3 Qualitative example, demonstration 3 Qualitative example, demonstration 3 Qualitative example, demonstration 3 Qualitative example, demonstration 3 Qualitative example, demonstration 3 Qualitative example, demonstration 3 Qualitative example, demonstration 3 Qualitative example, demonstration 3

Medium

Qualitative example, demonstration 4 Qualitative example, demonstration 4 Qualitative example, demonstration 4 Qualitative example, demonstration 4 Qualitative example, demonstration 4 Qualitative example, demonstration 4 Qualitative example, demonstration 4 Qualitative example, demonstration 4 Qualitative example, demonstration 4

Fast

Qualitative example, demonstration 5 Qualitative example, demonstration 5 Qualitative example, demonstration 5 Qualitative example, demonstration 5 Qualitative example, demonstration 5 Qualitative example, demonstration 5 Qualitative example, demonstration 5 Qualitative example, demonstration 5 Qualitative example, demonstration 5

Turbo


Videos

The same model-agnostic policy transfers to T2V: on both Wan 2.1 and CogVideoX-v1.5, ZEUS establishes a new quality–efficiency frontier without introducing video-specific kernels or modifying the backbone.

On Wan 2.1, ZEUS achieves 29.00 PSNR and 0.117 LPIPS at 1.76× speedup; ZEUS-Fast reaches 2.24×. On CogVideoX-v1.5, ZEUS achieves 32.50 PSNR and 0.060 LPIPS at 1.71×; ZEUS-Fast reaches 2.00×. See the complete video results below.

Quantitative Results

Image evaluation uses 5,000 MSCOCO-2017 validation prompts; video evaluation uses Penguin Benchmark prompts optimized as provided by the VBench team. Video baseline numbers follow the reported SVG-series setup. Similarity metrics compare accelerated samples with full evaluation; video metrics are frame-averaged.

ZEUS approximates the middle 70% of the trajectory, keeping the first 20% and last 10% as full evaluations. The main image presets Medium / Fast / Turbo use r = 2 / 3 / 4 consecutive reduced steps. Swipe within a table on small screens to see every metric.

Image generation

Image quality vs. speed on SD-2, SDXL, and FLUX. Higher is better for PSNR and speedup; lower is better for LPIPS and FID.

Full image results
Image quality vs. speed on SD-2, SDXL, and FLUX. Bold indicates best and underlined indicates second best within each model and scheduler block.
ModelSchedulerMethodPSNR ↑LPIPS ↓FID ↓Speedup ↑
SD-2DPM++DeepCache17.700.2717.831.43×
SD-2DPM++AdaptiveDiffusion24.300.1004.351.45×
SD-2DPM++SADA26.340.0944.021.80×
SD-2DPM++ZEUS-Medium25.720.1044.461.85×
SD-2EulerDeepCache18.910.2397.401.45×
SD-2EulerAdaptiveDiffusion21.940.1737.581.89×
SD-2EulerSADA26.250.1004.261.81×
SD-2EulerZEUS-Medium25.370.1185.061.86×
SDXLDPM++DeepCache21.350.2558.481.74×
SDXLDPM++AdaptiveDiffusion26.160.1254.591.65×
SDXLDPM++SADA29.360.0843.511.86×
SDXLDPM++ZEUS-Medium29.170.0843.591.87×
SDXLDPM++ZEUS-Fast26.380.1295.391.93×
SDXLEulerDeepCache22.000.2237.362.16×
SDXLEulerAdaptiveDiffusion24.330.1686.112.01×
SDXLEulerSADA28.970.0933.761.85×
SDXLEulerZEUS-Medium28.660.0953.871.85×
SDXLEulerZEUS-Fast25.150.1536.471.93×
FLUXEuler (Flow)TeaCache19.140.2164.892.00×
FLUXEuler (Flow)SADA29.440.0601.952.02×
FLUXEuler (Flow)ToCa17.700.3528.841.52×
FLUXEuler (Flow)TaylorSeer15.360.43010.083.13×
FLUXEuler (Flow)DiCache22.390.270/3.22×
FLUXEuler (Flow)ZEUS-Medium30.190.0471.532.09×
FLUXEuler (Flow)ZEUS-Fast26.770.0792.492.47×
FLUXEuler (Flow)ZEUS-Turbo21.800.1714.523.22×

Video generation

The same model-agnostic policy transfers to T2V: on both Wan 2.1 and CogVideoX-v1.5, ZEUS establishes a new quality–efficiency frontier without introducing video-specific kernels or modifying the backbone.

Full video results
Quality & efficiency on video generation. Higher is better for PSNR, SSIM, and speedup; lower is better for LPIPS. Bold indicates best and underlined indicates second best within each model.
ModelMethodPSNR ↑SSIM ↑LPIPS ↓Speedup ↑
Wan 2.1SpargeAttn20.520.6230.3431.44×
Wan 2.1SVG22.990.7850.1991.58×
Wan 2.1SVG225.810.8540.1381.58×
Wan 2.1SVG2-Turbo23.680.7890.1961.89×
Wan 2.1ZEUS (Ours)29.000.8460.1171.76×
Wan 2.1ZEUS-Fast (Ours-Fast)26.590.7920.1792.24×
CogVideoX-v1.5DiTFastAttn23.200.7410.2561.56×
CogVideoX-v1.5Minference22.450.6910.3041.48×
CogVideoX-v1.5PAB22.490.7400.2341.41×
CogVideoX-v1.5SVG29.990.9100.1122.28×
CogVideoX-v1.5ZEUS (Ours)32.500.8930.0601.71×
CogVideoX-v1.5ZEUS-Fast (Ours-Fast)30.970.8760.0732.00×

Generation quality beyond similarity

For image generation with FLUX.1-dev, over 200 COCO prompts, ZEUS differs from the full-evaluation baseline by only 0.0004 CLIPScore and 0.0061 ImageReward while achieving a 2.09× end-to-end speedup.

CLIPScore, ImageReward, and VBench results
FLUX.1-dev: 200 COCO prompts. Higher is better for CLIPScore, ImageReward, and speedup.
MethodCLIPScore ↑ImageReward ↑Speedup ↑
Full0.31161.09911.00×
SADA0.31131.08082.02×
ZEUS0.31121.09302.09×
Wan2.1-14B: balanced VBench-24 subset, with eight prompts each for subject consistency, motion smoothness, and temporal flickering. Higher is better.
MethodSubject ↑Motion ↑Flicker ↑Imaging ↑
Full0.96190.98100.97370.6118
ZEUS0.96280.98200.97550.6008
Δ (ZEUS − Full)+0.0009+0.0010+0.0018−0.0110

Ablation studies

ZEUS is solver-agnostic: it operates on denoiser outputs and can be paired with numerical solvers of different orders.

Few-step sampling and higher-order solvers
Ablation study on few-step sampling across schedulers. Results on MS-COCO 2017.
ModelSchedulerStepsLPIPS ↓FID ↓Speedup ↑
FLUXEuler500.0471.532.09×
FLUXEuler250.0402.651.58×
FLUXEuler150.0362.471.22×
SDXLEuler500.0953.871.85×
SDXLEuler250.0644.981.46×
SDXLEuler150.0654.721.20×
SDXLDPM++500.0843.591.87×
SDXLDPM++250.0665.281.45×
SDXLDPM++150.0664.871.20×
Ablation on higher-order solvers.
SolverPSNR ↑LPIPS ↓FID ↓Speedup ↑
Euler-128.660.0953.871.85×
DPM++-229.170.0843.591.87×
DPM++-329.050.0793.281.88×

Memory footprint on a larger backbone

FLUX-2-dev (64B), 4-bit quantization
Memory footprint ablation on FLUX-2-dev (64B) with 4-bit quantization. This is a separate model and quantization setting from the FLUX.1-dev main results.
SettingSpeedup ↑Peak memory (MB) ↓PSNR ↑SSIM ↑LPIPS ↓
ZEUS (Medium)2.07×2337031.5930.9380.029
ZEUS (Turbo)3.34×2337023.1150.8110.114

BibTeX

@inproceedings{wang2026zeus,
  title = {{ZEUS}: Accelerating Diffusion Models with Only Second-Order Predictor},
  author = {Wang, Yixiao and Jiang, Ting and Shao, Zishan and Ye, Hancheng and Sun, Jingwei and Ma, Mingyuan and Wang, Qinsi and Zhang, Jianyi and Chen, Yiran and Li, Hai},
  booktitle = {Proceedings of the 34th ACM International Conference on Multimedia},
  year = {2026},
  doi = {10.1145/3767308.3836067}
}